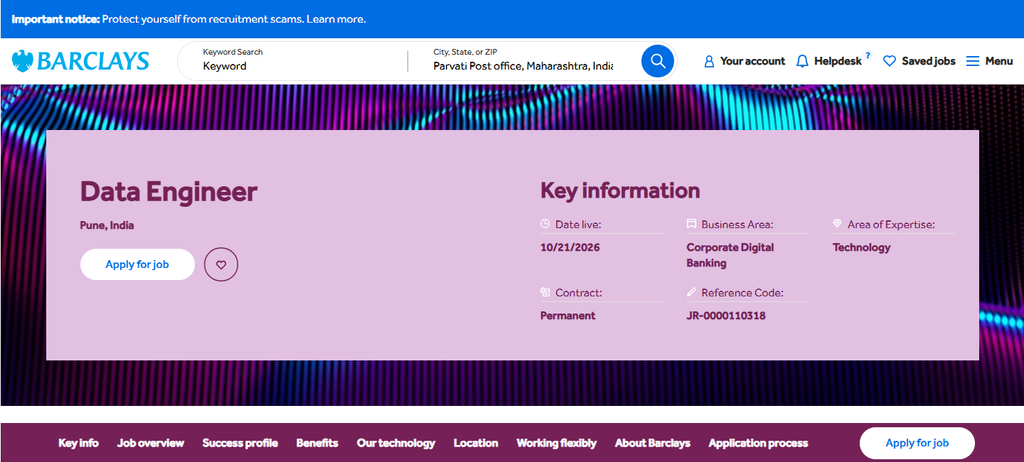
Are you an experienced data engineering professional looking to work on cloud data platforms and real-time financial data processing? Barclays is hiring a Data Engineer in Pune, Maharashtra, for its Corporate Digital Banking business area. This permanent technology position focuses on building scalable data pipelines, processing financial messages, and delivering reliable data solutions using modern cloud and streaming technologies.
🏢 About the Company: Barclays
Barclays is a major UK-based financial services organisation providing banking and financial products to individuals, businesses, and institutions. Its operations rely on secure technology platforms, reliable data processing, and robust risk and control practices.
📋 Job Overview: Barclays Data Engineer
- 🏢 Company: Barclays
- 💼 Job Title: Data Engineer
- 🆔 Reference Code: JR-0000110318
- 📍 Location: Pune, Maharashtra, India
- 🏦 Business Area: Corporate Digital Banking
- 💻 Expertise: Technology
- 📄 Employment Type: Permanent
- 📅 Date Posted: October 21, 2026
- ☁️ Core Technologies: Databricks, AWS, Snowflake, Kafka, Apache Flink, Spring Boot, and Spring Kafka
- 📨 Data Formats: ISO 20022 XML, SWIFT MT, JSON, flat files, and AVRO schemas
🌟 Why Is This Role Good for Experienced Professionals?
- 🚀 Advanced data engineering: Build and maintain scalable pipelines and cloud-based data products.
- ⚡ Real-time processing: Work with Kafka Streams, Spring Kafka, and Apache Flink to process events efficiently.
- 🏦 Financial domain exposure: Develop an understanding of payment messaging formats and banking data workflows.
- ☁️ Cloud platform experience: Apply Databricks, AWS, and Snowflake knowledge to data processing and storage.
- 🧪 Engineering quality: Use JUnit 5, Mockito, integration tests, code reviews, and structured troubleshooting to improve reliability.
🛠️ Skills Required
- 🗄️ Databricks and AWS: Creating data products, orchestrating pipelines, scheduling jobs, and working with cloud-based data solutions.
- ⚡ Kafka and Apache Flink: Event processing, stateful transformations, joins, aggregations, windowing, checkpointing, and state management.
- ☕ Java and Spring: Strong Java fundamentals, Spring Framework, Spring Boot, and Spring Kafka.
- 🏦 Financial message processing: Parsing ISO 20022 XML and SWIFT MT messages, handling JSON and flat files, and transforming hierarchical data into AVRO schemas.
- 🔄 Enterprise messaging: Integrating source systems through Kafka topics, IBM MQ, or JMS.
- 🧪 Testing and debugging: JUnit 5, Mockito, integration testing, ELK Stack, and application-log analysis.
- ❄️ Data platforms: Knowledge of Snowflake, data lakes, data warehouses, and data mesh concepts.
🎯 Expected Interview Rounds at Barclays
- 📝 Round 1: Recruiter / Initial Screening
- 💻 Round 2: Technical Interview – Java, Data Engineering and Streaming
- 🏗️ Round 3: System Design / Real-Time Data Pipeline Discussion
- 🤝 Round 4: Hiring Manager / Values and Leadership Discussion
📚 Preparation Tips for This Specific Role
- ⚡ Practise Kafka and Flink scenarios: Explain partitions, consumer groups, event ordering, windowing, stateful processing, checkpointing, and recovery from failures.
- 🏦 Study financial message formats: Understand the structure and purpose of ISO 20022 and SWIFT MT messages, plus how parsers handle invalid or incomplete input.
- 🧩 Design a transformation pipeline: Practise flattening nested XML or JSON into a target AVRO schema while handling missing fields, schema evolution, and validation.
- ☁️ Revise Databricks and AWS: Prepare to discuss pipeline scheduling, failure recovery, data quality checks, monitoring, and access controls.
- 🔎 Practise troubleshooting: Describe how you would use logs and ELK tools to investigate message-processing delays or failed events.
- 🛡️ Demonstrate risk awareness: Discuss data accuracy, auditability, secure handling, operational controls, and safe deployment practices.
📝 Resume Tips for Applicants
Tailor your resume to real-time data engineering and financial data processing. Highlight hands-on experience with Java, Kafka, Flink, Databricks, AWS, Snowflake, and Spring Boot where applicable. Include measurable outcomes such as improved pipeline latency, increased processing throughput, reduced failures, or better data quality, but only where you can substantiate them.
Mention testing practices, monitoring, incident resolution, and production support. If you have used SWIFT, ISO 20022, IBM MQ, AVRO, or Prowide Core, give these skills clear visibility. For an AVP-level position, also demonstrate technical ownership, stakeholder communication, mentoring, risk management, and leadership contributions where relevant.
💰 Expected Salary Range
The job description does not disclose an official salary band. Compensation for a Pune-based AVP-level data engineering position can vary considerably depending on experience, role scope, and leadership expectations. Treat any online estimate as indicative and confirm the expected compensation directly with the recruiter.
📩 How to Apply
👉 Application Link: Click Here
🤝 Referral Tip
Want to improve your chances of getting noticed?
Connect with someone at Barclays and request a referral—it can significantly enhance your visibility in the hiring process.
Candidates should search for Barclays Data Engineer – Reference JR-0000110318 on the official Barclays careers portal and review the requirements before submitting their application. Ensure the resume highlights relevant data engineering, streaming, cloud, testing, and financial messaging experience.
🌟 Final Thoughts
This Barclays opportunity is suited to data engineering professionals interested in combining cloud platforms, real-time streaming, and banking data workflows. Strong Java and streaming fundamentals, reliable pipeline design, financial-message processing knowledge, and a risk-aware engineering mindset can help candidates prepare effectively for the selection process.