📢 Hiring Alert: JLL Technologies is expanding its data engineering team and hiring experienced professionals for Data Engineer 2 and Senior Data Engineer positions in Bengaluru. These opportunities focus on cloud-based data pipelines, Azure data services, Python, streaming technologies and AI-driven engineering solutions.
📋 Job Overview
- 🏢 Company: JLL Technologies
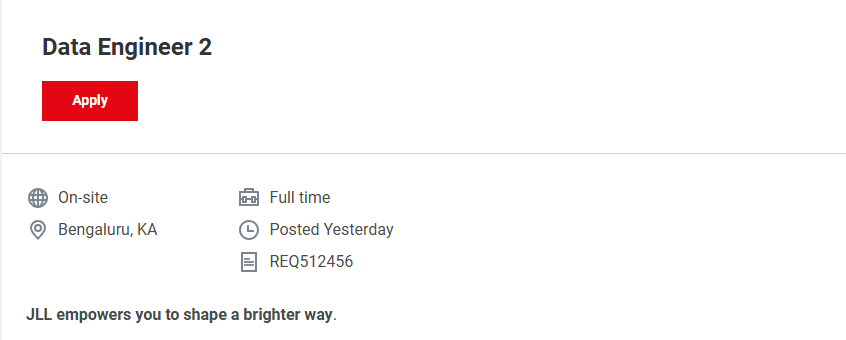
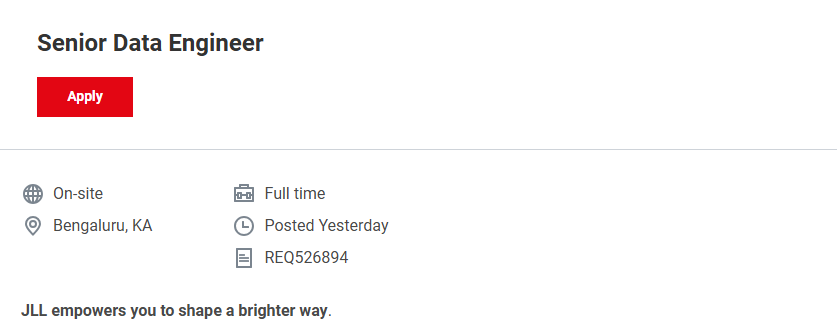
- 💼 Positions: Data Engineer 2; Senior Data Engineer (2 openings)
- 📍 Location: Bengaluru, Karnataka
- 🏢 Work Arrangement: The hiring announcement states hybrid work with two days per week in the office; the individual job listings show “On-site.” Confirm the actual arrangement with the recruiter.
- 🕒 Employment Type: Full-time
- 🎯 Data Engineer 2 Experience: 3–6 years advertised; the detailed listing requires 3+ years overall experience
- 🚀 Senior Data Engineer Experience: 6–10 years advertised; both detailed listings require 6+ years overall experience
- 🧩 Core Technologies: Azure Data Engineering, Databricks, Azure Data Factory, Python, PySpark, SQL, Kafka, Spark Streaming and cloud data pipelines
- 🤖 AI Focus: AI implementation, AI-assisted development tools and, for senior roles, AI-powered solutions and agent development
- 🆔 Job IDs: REQ512456 (Data Engineer 2); REQ512460 and REQ526894 (Senior Data Engineer)
🏢 About JLL
🌐 JLL (Jones Lang LaSalle) is a global commercial real estate and professional services company. Its technology teams develop digital capabilities and data-driven solutions to support business operations, property services and decision-making.
🌟 Why Are These Roles Good for Experienced Professionals?
☁️ 1. Strong cloud engineering exposure: Azure data services, data lakes and cloud-based pipeline development can deepen practical skills in modern data platforms.
⚡ 2. Real-time data processing: Kafka, Spark Streaming and Azure Event Hubs provide opportunities to work with event-driven architectures and streaming workloads.
🤖 3. AI-focused engineering: The listings mention AI tools such as Cursor, Databricks Assistant, Claude and, in one senior role, Databricks Genie. Senior candidates can also demonstrate AI-powered solution design and agent development knowledge.
🏗️ 4. End-to-end ownership: The work includes data architecture, persistence, pipeline development, storage and operational reliability—not simply writing isolated queries.
🛠️ Skills Required
- 🐍 Python: Data processing, scripting, reusable modules and pipeline development.
- ⚡ Apache Spark and PySpark: Distributed processing, transformations, optimisation and streaming concepts.
- ☁️ Azure Data Services: Azure Data Factory, Azure Data Lake Storage, Azure SQL, Azure Event Hubs and Azure Search.
- 🔄 Kafka and Event-Driven Pipelines: Topics, producers, consumers, queues, streaming events and failure handling.
- 🗄️ Databases: Relational databases alongside Cosmos DB, MongoDB or similar NoSQL technologies.
- 🧱 Data Architecture: Data lakes, structured and unstructured data, storage design, data persistence and scalable pipeline patterns.
- 🤖 AI Tools: Practical familiarity with AI-assisted development tools and their responsible use in engineering workflows.
- 🔐 Cloud and Distributed Systems: Understanding of microservices, security, networking and cloud operations is particularly relevant for senior candidates.
🎯 Expected Interview Rounds
Note: These are likely preparation stages based on the job descriptions, not confirmed official JLL interview rounds for these requisitions.
- 📞 Round 1: Recruiter Screening
- 💻 Round 2: Technical Data Engineering Interview
- 🧩 Round 3: Practical Coding or Pipeline Design Assessment
- 🤝 Round 4: Hiring Manager or Senior Technical Discussion
💰 Expected Salary Range
The job details supplied do not disclose official compensation bands. As a broad, indicative estimate for Bengaluru data engineering roles, candidates might consider ₹10–20 LPA for Data Engineer 2 and ₹18–35 LPA for Senior Data Engineer. Actual compensation can vary significantly with relevant experience, cloud expertise, streaming skills, AI implementation experience and the final level offered. These figures are estimates, not confirmed JLL salary ranges.
📚 Preparation Tips
- 🐍 Practise a Python pipeline: Build a workflow that reads data, validates records, transforms fields and writes results to storage, with logging and error handling.
- ⚡ Revise Spark and PySpark: Explain transformations versus actions, partitioning, joins, shuffles and strategies for improving performance.
- 🔄 Prepare a Kafka scenario: Describe how you would process events reliably, handle duplicate messages and recover from consumer failures.
- ☁️ Design an Azure pipeline: Explain how Azure Data Factory, Data Lake Storage, Databricks and Azure SQL could work together in a batch-processing solution.
- 📊 Practise SQL: Revise joins, window functions, aggregations, CTEs and methods to troubleshoot slow queries.
- 🤖 Prepare an AI use case: Explain how you have used—or would evaluate—an AI coding assistant to accelerate development while checking correctness, security and maintainability.
📄 Resume Tips
- 🎯 Match the correct level: Emphasise pipeline implementation for Data Engineer 2; highlight architecture, reusable frameworks, operational ownership and technical leadership for senior roles.
- 📈 Quantify outcomes: Include genuine metrics such as data volume, pipeline runtime, failure reduction, processing frequency or cloud cost improvements.
- ☁️ Name relevant services: Clearly list the Azure services, Spark technologies, databases and streaming tools you have used hands-on.
- 🤖 Show practical AI exposure: Describe a real implementation or prototype, the problem it addressed and how you validated the output.
📩 How to Apply
Apply for the position matching your experience using the job IDs below:
👉 Application Link (Data Engineer 2): Click Here
👉 Application Link (Senior Data Engineer): Click Here
👉 Application Link (Senior Data Engineer): Click Here
- Data Engineer 2: REQ512456
- Senior Data Engineer: REQ512460
- Senior Data Engineer: REQ526894
✅ Final Reminder: Data Engineer 2 is intended for professionals with 3+ years of experience, while the senior openings require 6+ years. Azure data engineering, Python, streaming, scalable pipelines and demonstrable AI exposure are important themes to prepare for.